
AI Inference Location Decisions: Cloud, Edge, and Hybrid Patterns for Electronics Engineering
Deciding where AI work happens is not only a software choice; it changes bill of materials, support burden, user experience, and long-term operating cost. The cloud-versus-edge trade-off first framed in December 2022 remains useful as a review method for electronics systems: compare latency, privacy, reliability, and memory growth before committing to a product architecture.
Server-side processing: benefits and friction
A simple way to reduce device complexity is to move processing, memory, or storage demand to connected resources. Cloud services can make a small hardware product appear more capable, but every transferred workload must be checked against user needs and total cost.
- Network roundtrip can add noticeable delay when raw data leaves the device and results come back. That delay is unacceptable for tasks such as self-driving decisions, which is why they remain local.
- Personal data raises privacy questions, especially baby cam material. Encryption and access controls matter, but so does whether the data leaves the user's home.
- If a connection fails, features that cannot run locally may stop working.
- Fixed hardware cost may become variable spend, including server usage fees such as AWS plus bandwidth. The expense tracks users, usage, and every connected device in a customer's setup.
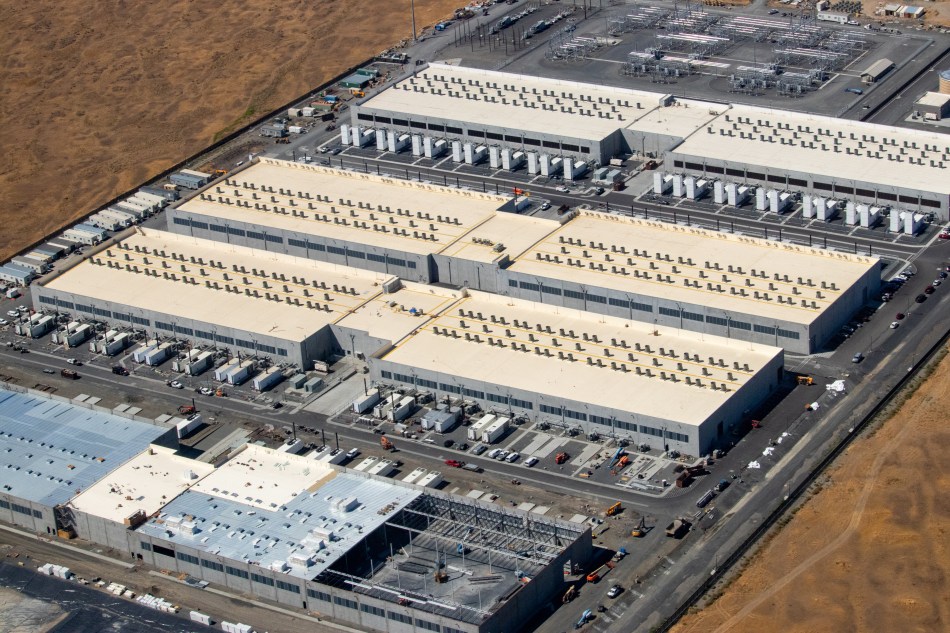
The reasoning from December 2022 still matters, nearly four years later, and public concerns around AI infrastructure have broadened. The earlier hyperscale build-out was still early. A portion of new compute capacity was aimed at cryptocurrency mining before being redirected to deep learning. The larger data-center footprint is now more visible.
Infrastructure pressures relevant to engineers
- Financing patterns can be circular. A supplier may back a developer that commits to buying that supplier's chips and software. This can feed stock-market volatility and bubble market anxiety.
- Tax breaks and incentives may be used to attract facilities even when local jobs mostly end after construction.
- Incremental electricity demand often requires additional generation, with costs shared widely.
- Added supply is frequently hydrocarbon-based, bringing pollution and noise objections.
- Cooling requires sizeable water, redirecting or draining aquifer reserves from fresh, recycled, or mixed sources.
- Campuses consume open land and agricultural fields.
These effects influence permitting, operating assumptions, energy budgeting, and whether cloud-dependent product features remain viable over a long lifecycle.
Edge and tethered local models
The late 2022 analysis considered a tethered local device, commonly wireless, as another way to slim hardware. A smartphone or tablet can provide compute, storage, imaging, and networking. The host is already purchased, and it may also carry remaining cloud bandwidth cost. Local tethering usually reduces latency versus pure cloud processing, limits direct provider data exposure, and can keep personal data out of training datasets. It may also reduce ongoing subscription or token expenses.
This approach creates a software-maintenance problem: companion applications must support Android, iOS, and iPadOS across their device variations and continue to track platform changes. If support falls behind, the accessory can become impractical.
The hidden hardware consequence is local capacity. Reusing a smartphone can avoid duplicate camera and processing parts, but it pushes demand into nonvolatile storage, volatile memory for code execution, and temporary data handling.
Example model footprints make the point clear. Gemini AI models in latest-generation Chrome browser installs require at least 4 GBytes. Apple Intelligence included with iOS 27 is now required, unlike the optional approach in version 26, and uses up to 14 GBytes. The default AI model suite in MacOS 27 is 12-30 GBytes, although open-source alternatives can relieve some pressure.
Compression changes the slope but not the trend. PrismML focuses on quantization and related compression for constrained systems. For the Alibaba Qwen3.8 27B open-source model, it achieved between 9-10x shrinkage while still matching 98% of Qwen aggregate benchmark scores, yet the resultant model was still 5.9 GBytes. Perplexity Portable Computer for local model storage and processing is 20 GBytes.
Hybrid execution and local networking
Not all workloads should move away from servers. Some latency and privacy concerns can be mitigated with encryption or other controls, while the need to access a large trained model remains decisive. In those situations, server capacity is still central, as the late-2024 follow-up coverage observed.
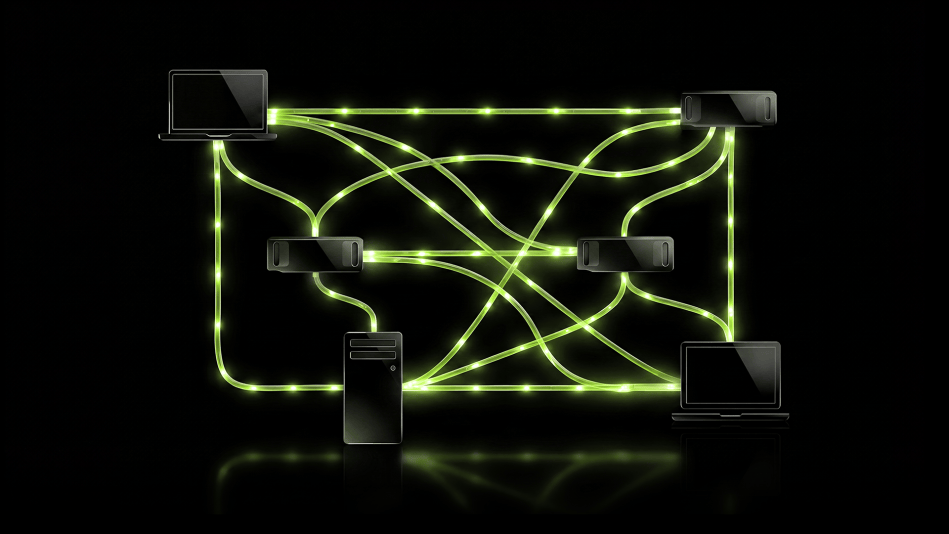
A more realistic direction is hybrid execution: simple, safety-sensitive, or privacy-sensitive tasks stay local, while heavier model-dependent functions escalate on demand. Local networking also expands the idea. NVIDIA Personal AI Router, or PAIR, distributes inference and agent processing across multiple LAN-connected computers, including non-NVIDIA Macs. Shared NAS storage can hold models for several devices, although limited RAM will usually prevent the NAS from performing full inference.
The training-versus-inference split further explains resource placement. Data centers also support training, retraining, expanded dataset work, and transfer learning. OpenAI reported that the Astra training run for its latest-generation Astra GPT-6 fully consumed more than 100,000 GPUs. Training is highly parallelizable, so GPU-derived architectures remain dominant. In inference, prefill is the more parallel portion; decode is memory-bound, reinforcing demand for advanced HBM capacity and bandwidth.
Common misconceptions
- Edge processing is always cheaper. It may lower recurring cloud spend but increase flash, DRAM, validation, and companion-app maintenance.
- Cloud offload can be added without architectural cost. If roundtrip delay or lost connectivity breaks the core experience, the placement is wrong.
- Using a phone guarantees privacy. It limits direct cloud transfer, but app design, OS controls, updates, and user settings still matter.
- Compression removes capacity concerns. A reduced model can still require 5.9 GBytes or 20 GBytes.
- Hybrid simply means caching. Often, local processing owns safety, privacy, or offline behavior, while cloud resources supply model scale.
Practical checklist
- Map each AI function against latency, privacy, connectivity tolerance, reliability, and model scale.
- Decide which data should remain on-device or on the local network, including baby cam or other household personal inputs.
- Convert recurring cloud spend into a product-lifecycle cost, covering AWS-style fees, subscriptions, tokens, and bandwidth.
- Estimate local storage, DRAM, and temporary-data needs for current and future requirements.
- Confirm Android, iOS, and iPadOS support, plus a plan for operating-system and hardware changes.
- Evaluate compression by residual footprint, not only shrinkage ratio.
- Define hybrid escalation and offline fallback before architecture lock.
- Review LAN routing and NAS sharing for model storage, but verify RAM limitations.
FAQ
Why are autonomous vehicles a classic edge case?
They need immediate decisions and cannot rely on network roundtrip time. Local processing keeps function and safety inside the vehicle.
Does local processing reduce privacy exposure?
Frequently, yes. Personal material such as baby cam data can remain nearer the user, and provider training access may be reduced. Encryption and app governance remain necessary.
Why does edge AI stress memory and storage?
Models, runtime code, and temporary data all need local capacity. The client-side requirements increase as features become standard.
Will one architecture win everywhere?
Unlikely. The field is moving toward split execution, local-networked options, and server use where large trained models are essential.
For Electronicseng readers, the useful conclusion is to treat inference location as an engineering review problem. A balanced design considers cloud, edge, and hybrid placement together, making the path from introductory features to scalable systems more defensible.